Alert when a Docker container stops or is unhealthy
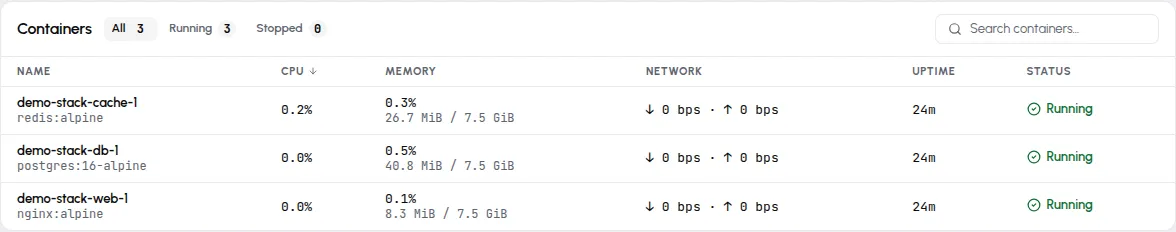
Get told when a container on any of your servers dies or its healthcheck starts failing, without an exporter, a Prometheus rule, or a script of your own. The Containers panel on a server’s page lists that server’s Docker containers with live CPU, memory, and network figures, and two alert rules watch them. There is nothing to configure: the agent probes the Docker socket on every collection cycle, so the panel appears on its own about a minute after the agent can reach Docker.
What the panel shows
Section titled “What the panel shows”The header filters the table by state (All, Running, Stopped, each with its count) and has a search box; each container is a row:
- Name and image — Compose-managed containers carry their Compose
names (
demo-stack-web-1), and the agent also reports the Compose service and project labels. - CPU and Memory — memory shows the percentage and the usage against the container’s limit (the server’s total memory when the container is unlimited).
- Network — current ↓/↑ rates in bits per second (running containers only).
- Uptime and Status.
Stopped containers stay on the list for 24 hours — long enough to notice a container that died overnight.
Container CPU is per core
Section titled “Container CPU is per core”Container CPU percentages mean the same thing as in docker stats, not
the same thing as the server’s CPU panel. The gauge’s own tooltip states
it: “% of a single vCPU. 100% = one core fully used; containers using
multiple cores can exceed 100%.”
So on a 4-core server, a container pinning every core reads 400% — a busy container, not a broken chart. The server’s own CPU panel stays on the 0–100% whole-server scale.
Alert when a container stops or turns unhealthy
Section titled “Alert when a container stops or turns unhealthy”A container that stops is caught by Container down, and one whose healthcheck fails by Container unhealthy. Both are on by default on every alert template:
- Container down fires when a container stops without a clean exit.
Exit code 0, or 143 from a
docker stophonored with a graceful shutdown, counts as intentional and fires nothing, and a container running for less than 2 minutes gets a grace period, so deploys and restarts stay quiet. - Container unhealthy fires when the container’s own Docker
healthcheck reports unhealthy, so it applies to containers that have
one, whether from the image,
docker run --health-cmd, or a Composehealthcheck:.
Each incident is opened per container and named after it. It resolves on the first check that sees the container running (or healthy) again, and silently when the container is removed. Switching either rule off, or routing container alerts to their own channel, happens in the template editor; Set up one alert walks the clicks.
If containers don’t appear
Section titled “If containers don’t appear”When Docker is present but the panel says “No containers detected on this
server”, the usual cause is that Docker was installed after the
agent. The install script adds the agent’s user to the docker
group only if that group exists at install time — installing Docker later
leaves the agent without permission to read the socket.
Grant it and restart:
usermod -aG docker monitorablesystemctl restart monitorable-agentThe panel fills on the next collection cycle, within about a minute. (Re-running the install command does the same as part of an upgrade.) What the agent reads from the socket — and the container fields it never touches, like environment variables and commands — is listed in What the agent collects.